Wednesday, 29 June 2016

Diversifying bias: how dataset bias can hurt and what we can do about it

A very important topic for consideration, the question of dataset bias has been getting into the mainstream more and more recently: e.g. "Why we should expect algorithms to be biased", and
"Artificial Intelligence's white guy problem".

As a research curiosity, dataset bias has been shown to affect model generalizability: a machine learning algorithm trained on one dataset, and receiving flying colors on a particular collection of test images, may have abysmal performance on a different dataset with different image statistics. You can think about this as the case of only ever seeing faces front and center in an image, and then being tested on off-center faces and realizing you are unexpectedly, but miserably, failing at detecting them. Some real-life examples: "HP investigates claims of racist computer", "Camera misses the mark on racial sensitivity".

http://www.selfieresearchers.com/wp-content/uploads/2014/09/CV-Dazzle-antiface.png


A more relevant and pressing example concerns the self-driving car. Ultimately, if trained correctly, it will learn to avoid pedestrians, lamp posts, barriers, and whatever else was meticulously labeled and included into its training set. But will it know to avoid a kangaroo if the most it ever saw in its training data and prior experience is a deer or a cow? For an algorithm to be capable of this type of generalization is a reasonable expectation. So even though the car might not be able to accurately determine what is happily hopping across the street, it will guess that it is a bit of a deer and a bit of a cow and since it is upright, maybe a bit of a pedestrian as well... but overall, and most importantly, whatever its identity, this happy creature should not be run over.

Speaking of cows...

Let me make an aside here and say that the sole fact that our machine learning algorithms (the ones behind the self-driving cars, autonomous appliances and robots of the future) are increasingly relying on data (are "data-driven") and are increasingly likely to be neural networks (which happen to chug through and learn from large amounts of data very well) is not in itself a reason for concern. I do not buy the argument that we should fear our "black box algorithms" because they are parameter-bloated, connected and intertwined networks that are "hard to understand and harder to interpret". Until quite recently, when asked what computer vision was up to, I would sarcastically answer: "detecting cows on fields... but only patched ones, on green fields, in the center of the image, and only if awake". We wouldn't even be having some of these conversations (in the media) about dataset bias if neural networks weren't performing this well (there are bigger problems at stake if even the cows can't be detected). Having large amounts of data and the architectural machinery to deal with it is precisely what is helping us learn and generalize better.

With that aside, it is nevertheless crucial to start thinking more carefully about dataset bias and model generalization. This thinking should not pit us against data-driven algorithms in any way; rather, we should continue to remind ourselves that it is the great prediction potential of the algorithms that is granting us the opportunity to think about these questions in the first place.

There is no doubt that our current, state-of-the-art models are suffering from bias in their datasets. Otherwise, Google wouldn't have made a headline that was centered around how well its algorithm could recognize cats (as opposed to anything else, really) by learning from YouTube videos. DeepDream wouldn't be imbuing every single photo with hallucinogenic dogs. Microsoft's AI chatbot wouldn't have learned in the span of only a day that being a racist asshole gets people's attention. Researchers wouldn't be spending their time fooling the algorithms. The list goes on.


The problem is that this kind of dataset bias is unavoidable - because people are biased and they are the source of the data that we're feeding to our algorithms (and if we can learn anything from the above, it's that people seem to be biased towards putting others down on social media, but then compensating by flooding the net with pictures of cute animals). This means that, unwillingly, we may be imbuing our algorithms with negative qualities, behavior, and biases. We may be perpetuating biases that we would otherwise like to remove from society (see "When algorithms discriminate").

And yet, when we try to actively interfere, we can make the problem worse. More frighteningly, if people know they can influence and have effects on the data, they may use this for their benefit, and this can have either positive or negative consequences for other members of society (as in this Ted Talk on the "Moral bias behind your search results"). We are all responsible for the data that we put on the net (what we upload and what we search), and need to recognize that the biases that are out there are our own.

But if the biases do get out there, should we get rid of them? What would "un-biasing" the data even mean? Who has the right to say that something should or should not appear in a search result? Would a top-down filtering of content, that would change the data everyone sees, even be appropriate? Most parents would disagree with a single, universal parental control for all of the world's children, and this is not much different. Different individuals, cultures, societies have different preferences and norms, different beliefs and taboos.

Which brings me to the importance of diversity in the data that we have. I would not argue for artificially nudging the numbers or tweaking the data to try to eliminate certain kinds of biases, as this can have all sorts of secondary and unintended consequences (as the Twitter example has shown). Instead, the more people that are participating in the data that is being harnessed for training algorithms, the better. This naturally adjusts the data balance to more accurately reflect the population that is using it. One solution is just to put more people on the web, and I think we will get there. Another is to bring more humanities folks into the tech loop. It would be great to have the perspective of anthropologists, sociologists, historians, policy and law makers, and psychologists for insights on cultural sensitivities, historical trends, crowd mentality, virality, societal pressures, etc. so that we can have better expectations of what the data may bring before its on our plates and we have to deal with the consequences. In this case, the suggested approach is to use this knowledge to adjust the data-collection procedures themselves rather than the data after-the-fact.

If you were collecting a survey, a change in wording but not meaning might drastically change who would respond to it. How different cultures look at concepts like success, individuality, and norms are also crucially different and affect how and what they communicate about these topics. Take this simple example: say you collect perceptions about an exam from a group of schoolchildren. You get two answers: "it was easy! [secondary reason: I passed]", "it was ok [I think I got only 98%... where did the 2% go?]". Without knowing the context of the cultures, societies, or families from which these two responses came, you would have a very biased dataset (I'm reminded of Malcolm Gladwell's book Outliers; or this talk). And this extends beyond surveys. The behaviors you elicit (and end up collecting) from a group of users can depend crucially on how information, a task, or a UI are presented. Psychologists and sociologists know this very well. But they are also less likely (currently) to be the ones collecting the large datasets that modern-day computational algorithms are trained on.

Questions of labeling are key. What do you call that thing? If you give it one label over another, a different set of properties or attributes might be retrieved. Consider an example: the labeling of street scenes. Here's a pedestrian, and another one. Here's a bicyclist. What about that person in a wheelchair? Is that a pedestrian or transportation device? How many body parts must be visible and moving for a pedestrian to be labeled as such? This labeling might affect how an algorithm analyzing the scene might predict the future movements of the participants and objects in the scene. This, in turn, might affect the decisions the algorithm (read: autonomous vehicle) makes.

http://fineartamerica.com/featured/psychedelic-city-pop-art-new-york-city-street-scene-miriam-danar.html

Every labeler is biased. Biased by their culture, their society, and their experience. Instead of attempting to unbias the labels, we should introduce even more biased labelers... to compensate (and please, let's throw something intellectual up on the net, at least once for every 100 cats...). We should increase the diversity of the bias until, on average, we get something reasonable. Ensembles work. That's the wisdom of crowds. 

And what do we do in the meantime while we wait for the whole world's wisdom to accumulate on the net? We think harder about our data collection strategies and the tasks used; we spend more time debugging and visualizing the algorithms and the trends they pick up on; we consider how to present, display, and use the data; we brainstorm ways to annotate and make explicit whether certain labels, tags, or content are more likely to be controversial or subjective; and we treat predictions in this space with greater care, and importantly, less confidence. Just as we tend to dislike the individuals with the greatest bias but highest confidence, let's not fill our digital world with these personalities.


Saturday, 27 February 2016

My free business lesson from an Uber driver


Want a free business class? Find out more about Uber (or try talking to more Uber drivers). Every Uber driver has at least some kind of opinion to share about the Uber business model (its upsides and downsides for drivers and passengers alike), and some drivers (if you are inquisitive) will provide you with additional business logistics. Occasionally you will receive an outlook on the (potentially sobering) present and future societal impacts of Uber. If you are really lucky, you will have spent the whole ride entertained by a detailed rundown of the business' history and how it has been continuously adapting to novel locations, changing consumer demands, and emerging competition. I found myself the lucky passenger of precisely the latter kind of Uber driver on my last trip from SFO to Palo Alto: a young latin American named Marcos, with a square jaw and an equally square baseball cap bill. I will endeavor to provide a recount of this conversation (really, a monologue punctuated by my occasional requests for additional details). I aim also for my recounting to have the properties of a conversation, in that regardless of the factual accuracy of individual details or the exact temporal sequence of events (potentially tainted by the knowledge of my driver and my interpretation), the general outlines of the high-level picture should nevertheless surface.

source: http://johnbracamontes.com/
From my driver Marcos I learned that Uber sprouted up in SF to fill an existing gap in the market: the need for a professional and, importantly, reliable chauffeuring service. An emerging sentiment at the time was one of dissatisfaction with cab services, passengers having to unwillingly deal with unreliable service and rude or disrespectful drivers. The drivers seemed to have the upper hand in this market and behaved accordingly. 
Although I am not sure how widespread this sentiment was, I can attest to the fact that this is the reason I've never liked taking cabs.

Naturally, this was the sort of inconvenience and unpleasantness that the more financially-privileged were willing to pay to avoid. Uber saw this opportunity, and was perfectly positioned to take advantage of it: in a city with (1) a dense population packed in a relatively small (drivable) area, (2) large and growing tech companies providing a continuous supply of financially-privileged individuals, and (3) a traditionally startup-friendly environment, where bold new ideas regularly surface and are picked up by the wave of tech hype. And so, Uber was born (in 2010). As a professional and reliable chauffeuring service with a convenient mobile app interface (and up-to-date updates on driver location), passengers would be picked up in shiny black cars by courteous drivers in formal attire, offering additional frills like water and mints for the on-the-run business man. Sure, this was an expensive alternative to cabs, but to the users of UberBLACK, it was well worth it. Behind the scenes the structure was quite clever as well: Uber provided the cars and phones for the drivers (equipped with Uber app and Google maps), and regular people stepped up to provide themselves as drivers, no formal interviewing procedure required. Marcos dropped out of his community college to take on this new, respectable job that required a full-time commitment. As the success of a personalized on-demand transportation service had shown its colors, it opened up the market for new variants. And this is where Lyft comes into the picture. 

source: techcrunch.com
Lyft aimed to capture another SF-based market segment: the young crowd of current students and recent graduates, now employed at local startups. An alternative transportation solution was needed for the kind of person that ate Mexican from a food truck and sported giveaway t-shirts acquired at hackathons and career fairs. Lyft was marketed as an affordable ride-share, the distinctive pink mustache on car bumpers trumpeting the friendly, hip, and easy-going atmosphere that customers would learn to expect from it. In stark contrast to UberBLACK, passengers would sit in the front, engage in conversations with their casually-dressed drivers, and ride in whatever car the driver happened to own. Whereas Uber lent its drivers cars and phones, Lyft sent them giant pink furry mustaches. The latter was more financially viable, allowing prices to drop to student standards, well below cab fees. Importantly, Lyft drivers could work on flexible schedules, squeezing in rides in the free moments of the day, morning, evening, and between activities. Marcos could now go back to college and pick up passengers in his free time. 
Uber wisely recognized that much of its infrastructure was already in place to allow its service to be differentiated for different kinds of customers. Uber then branched to provide a new option: UberX. Learning from the successes and failures of the Lyft model, UberX allowed drivers to work flexible hours in flexible attire, operating their own vehicles – provided, and this is important, that the vehicles passed some minimal quality standards (Lyft passengers had begun to complain about the run-down condition of some of the cars). The water and mints were still there. Drivers were encouraged to be friendly and hip. 

Uber had a first-player advantage: it had been first in the market and thus enough time to acquire a good reputation and loyal customers through its UberBLACK service. UberX brought in new customers and gave the old ones a flexible option. Provided with the same reliability and courteousness, some of UberBLACK customers now opted for the cheaper, more informal option. It is part of SF culture not to flaunt financial well-being, as evidenced by the casual hoodies and slacks regularly worn by some top tech executives. So black cars became regular cars (that were nevertheless guaranteed not to be run-downs).

As an aside, Uber now has a variant that is intermediate between UberBLACK and UberX. Do you want to get picked up by a casually-dressed Uber driver but in a brand-name car like a BMW or Mercedez for an intermediate price? Well now you can with Uber Select. And if you don't want a fancy car to pull up at your office entrance in SF, you can stick to UberX. Different Uber options happen to be dominant in different cities. For instance, perhaps unsurprisingly, LA tends to prefer the luxurious option.

After the introduction of UberX, Uber's customer pool grew. This meant that the density of ride requests was often higher on Uber than on Lyft. Drivers had more customers overall and could cover smaller distances between ride requests. Marcos and his friends signed back on with Uber.

source: techcrunch.com
New measures had to be taken. Lyft gave its drivers new incentives: “complete X rides and receive a rebate on the hefty commissions paid back to Lyft”. Uber followed suit. The new incentives served an additional purpose: having to complete a minimum number of rides, many drivers could no longer afford enough time to work for both companies and still complete enough rides with each. Choices had to be made. Uber tried to give drivers incentives for accepting all ride requests in a row. Drivers obliged and accepted all that came their way. They accepted requests even if it required going around the whole block just to pick up a passenger directly on the opposite side of the street. Passenger wait times increased. Passengers were not happy. Uber pivoted its incentives structure.

A vicious price war ensued. The water and mints disappeared from Uber cars. With few noticeable differences between the two services from the customer perspective, customers went where prices were lower. Lower prices meant more ride requests and a quicker way to hit the incentive ride minimum. Drivers went where there were more customers.

As Marcos prepared to drop me off in Palo Alto, he got his Lyft app ready. He said he'd take the first request he got - Uber or Lyft. Palo Alto has longer ride distances and fewer customers per square area than SF. Time is costly, and Marcos would not spend it passenger-less. After all, he needed to be in class soon. He let me out.  My half-hour, 21-mile ride cost $37.78, including a $3.85 airport surcharge. Uber would take 20-30%, gas would cost Marcos another few dollars, and car depreciation isn't to be forgotten either. Marcos told me that the prices are more expensive in SF than surrounding areas. (In fact, my trip back to SFO from Palo Alto 2 days later cost $28.47). On my Uber app, I gave Marcos 5 stars and left some feedback about what a knowledgable guide he turned out to be. Then again, I don't remember the last time I gave a poor review.
source: http://images.cdn.stuff.tv
Lowering prices means even more burden on the drivers. Already the fraction of a cab fee, Uber fees are reaching new lows. Two days later, I logged onto my Uber app at 5 a.m. to request a car back to the airport. I could see some cars circling around the Googleplex complex, 15 minutes from where I was. After about 2 minutes, an Uber driver accepted my request. Another minute later, he canceled the request. He'd probably gotten a more conveniently-located ride request and would make more money by keeping the distance driven without passengers minimal (and 15 minutes was already pushing it). His car stayed around the Googleplex complex. I placed another request, finding myself irritated that it was taking me longer than 5 minutes to get a car. My last dozen or so Uber trips involved instantaneous request acceptance, with a car picking me up 1-2 minutes later. How spoiled I had become. Finally, after another 3 minutes, my request was accepted by a middle-aged Latin American gentleman named Juan Carlos, and in 15 minutes, he was at my hotel.

I was really thankful to Juan for picking me up. He was surprised to find out there wasn't a swarm of cars ready to take me. Uber cars often outnumber passengers at this early time in the morning, he told me. I was in turn surprised to hear this, having spent that night tossing and turning in bed worried that no Uber drivers would be on the roads so early (I didn't even consider cabs as an alternative anymore). Our differing expectations for what would be the Uber availability situation that morning led me to thinking that there are too many variables at play to fully predict driver behavior. Uber drivers have to somehow optimize ride fares, company incentive structures, passenger availability, and competition with other Uber cars to figure out if a particular ride is going to bring them more than it will cost. Earlier that morning Juan had driven another passenger to San Jose airport - a 20 minute ride that cost the passenger $10, of which Juan would probably get less than $6-7.

I told Juan about one of my recent Uber experiences in Boston. I had decided to try UberPOOL for the first time: a variant where multiple passengers can share the same ride, with different initial and destination locations, as long as the trips are relatively in the same direction. Each passenger pays less in return for the potentially longer ride. If multiple passengers are picked up, the Uber driver can hope to make a sliver more in the same fraction of time by combining the trips. The interesting catch is: you get a guaranteed UberPOOL price regardless of whether another passenger is taken. In other words, you pay a lower price (even lower than UberX) just by agreeing to potentially share the ride. Talking to my other friends in Boston, it is pretty common for no additional passenger to show up. So my friend and I took an UberPOOL. We counted as a single passenger (it would be the same price if only one of us was there), but didn't end up picking up a third passenger on the way. Our ride was 10 minutes from Downtown Boston across the bridge to East Cambridge, and cost us a total of $6. Splitting it, each of us paid $3, almost the price of a subway ticket, but with the walking distance (from subway to house) cut from 15 minutes down to zero.

Who takes the loss when no additional passenger request is made on UberPOOL: the company or the driver? I asked Juan. Turns out, it's the driver (in Lyft's case, the company pays the difference). So if drivers are making so little money, how can Uber remain a viable longterm business model? Without missing a beat, Juan replied that it doesn't need to be viable for longer than a decade at the most. "After all, Uber is building a fleet of self-driving cars. No paid drivers will be needed." Juan paused. But there's a bigger problem: Juan is concerned about the strawberry-picking robots that are now working on farms day and night, 24 hours straight. Soon, there'll be even more robotic farm hands. Juan's family back in South America along with thousands of other people are going to be out of the farm jobs that provided their livelihood. "What happens then?"
Juan Carlos got some fraction of the $28.47 I paid via my Uber app, and 5 stars.

source: http://www.econlife.com

Further reading:

Dated sequence of events in Uber's history: http://techcrunch.com/gallery/a-brief-history-of-uber/slide/26/

Saturday, 13 February 2016

On effective communication: because it matters.

I've been thinking quite a bit recently about effective communication, party because there were 2 seminars last month at MIT about giving good talks (one by Patrick Winston, one by Jean-luc Doumont), party because we recently published a paper about what makes visualizations effective (for communicating messages), and partly because I've been TA-ing a research course for undergraduates (with a large communication component to it).

I'll summarize here some notes from the talks I went to, as well as my own thoughts and insights. Though I'm sure I'll have lots more to say on this topic in the future.

Patrick Winston started off his talk with the following statement*: "you (the researcher) will be judged first by your speaking, then by your writing, and finally by your ideas". This is a common phenomenon: a great communicator can sell you on the simplest ideas and make you see beauty in them; a poor communicator can obscure the most beautiful of ideas. Both examples regularly occur in lectures, in research talks, and in business presentations (but I'll focus on the researchers, here). It really is a shame when beautiful ideas don't come to light because the researchers behind them lack in explanatory artistry. It is an art, this whole communication business - which is why it is not commonly taught in a formal manner. Aside from the occasional seminar, the occasional resource exchanged among students, and the occasional tip given by one researcher to another during a practice talk, aspiring researchers (e.g. students) get no formal coaching and are told to "just do good work". Feedback and tips from advisors can be quite uneven, depending on the experience of the advisors themselves. (luckily, MIT professors are very good at selling their research, judging by the content on the front page of MIT news every morning; as Winston puts it: "your ideas should have the wrapping that they deserve")

The point is: many (esp. young) researchers need formal communication coaching, and often they underestimate how important it is for their careers (it pains me to hear yet another graduate student proclaim: "boy, these talks and posters I have to present are such a waste of my time"*). I would like to applaud MIT's initiative: the new EECS communication lab (and similar ones in other departments) for providing resources, training and advisors to students, when they need them. Additionally, I think MIT's SuperUROP course for undergraduates is a super valuable experience (essentially a how-to guide to being a researcher), where alongside a year's worth of academic research, students practice and receive feedback on important communication skills: writing research abstracts, proposals, and papers; performing peer reviews, creating academic posters, and giving research pitches and presentations. And yes, as a TA in the course, I sometimes hear the same excuses ("boy, all these written assignments are such a waste of my time, why can't I just do the research"). But when you're in an environment where industry representatives, senior researchers, and MIT faculty are following what you're doing (as is the case for these students), being able to sell your work can mean a lot for your future career. Last semester, for instance, the students participated in a large poster session, where they presented their work to all the aforementioned parties. I gathered some advice, common mistakes, and helpful suggestions in the linked-to set of slides.

* Yes, yes, groundbreaking ideas can speak for themselves, but I guarantee that most ideas need someone speaking for them (at least to get them off the ground).

Note that from one set of communication-related slides to another, from one talk to the next, the same kind of advice surfaces again and again. Most often, the views and suggestions presented are not idiosyncratic, but common, accepted, guidelines. We've all been in the audience: we know what catches our interest and what bores us to death (and it's often not the content to blame).

Let me summarize (and paraphrase in my own words) some of Winston's talk advice:

  • start with an empowerment promise: give your audience a sense that they will walk away with something (e.g. some newfound knowledge or ideas) from your talk, so they know what to look forward to and why they should care
  • get your idea out quickly, and cycle back: don't expect that all your audience members will follow along with you until the end, and do not leave the most important to last ("avoid the crescendo, just blurt it out"); come back to, and reinforce your points
  • use verbal punctuation: people fog out, so bring them back once in a while, especially to accentuate a switching of topics, slides, etc. (kind of like an "ehem, you can wake up now, even if you've missed the last few minutes, I'm starting a new thread..."); 
  • avoid near-misses: foresee what the audience could be confused about and clarify your contributions
  • what you end with is the last impression: make it count, clarify your contributions, show your audience what they're walking away with; and remember: the final slide will be there forever, "don't squander this real estate" (is your final slide the infamous and content-less "thank you"?)
  • whether a poster or a presentation, what should come clearly through are your vision, steps, and contributions (Winston even advocates naming the relevant sections/slides accordingly)
When approached once by a young researcher looking to get advice on his job-talk slides, Winston proclaimed: "too many slides and too many words". 
"How do you know?" the researcher asked.
"It's almost universally true."
(Winston later added that allowing powerpoint to have less than 30-point font is probably Bill Gates' biggest fault. When text has to shrink that much, there is too much of it on the slides.)

This is the kind of advice that will come up again and again. People have the tendency to cram as much as possible into very small (spatial or temporal) frames. Researchers want to talk about all the great work they've done (not realizing that they're drowning out the most important parts). Students put all the details of their projects on their posters (not realizing that the contributions get lost). Here's my suggestion: do one pass of the content from which you want to pull slides/talking points, and extract the most important points. Sleep on it. Then pick the most important points out of your selection, and scrap the rest. Repeat. With enough cycles, you would have cleaned away the debris, exposing the shine of the main ideas.

What I like about Winston's communication advice is that he comes at it from the perspective of a scientist (he is, after all, a computer science professor at MIT). Sprinkled throughout his talk are technical references and examples. Most of all, he emphasizes the importance of projections - the way an idea or a piece of work is communicated to an audience: the context, the stance, the voice, the presentation style, all of it.

Another individual with a great technical take on communication advice is Jean-luc Doumont (got a physics PhD from Stanford). Jean-luc (he prefers to be called by his first name) consistently refers to the importance of increasing signal and eliminating noise in a presentation, whether visual or oral. This concept is ever-present in his book: Trees, Maps, and Theorems - which I highly recommend. 

Note that "noise" can refer to many things at once. In the case of presentations, the noise is everything that is tangential to your main points - it is the 'ums' and 'likes' in your speech, the nervous pacing and awkward hand fidgeting, the excessive details on your slides (do you really need your institute's logo on every slide?). In the technical writing, noise includes all the superfluous words (why say it in 10 words when you can say it in 3? why talk like a politician?).

With regards to maximizing signal, Jean-luc also talks about maximizing effective redundancy - which is to say helping to carry the message across despite noisy channels (those you have no control over, like the audience's attention or knowledge; whereas noisy channels that you do have control over should be minimized). Redundancy can be verbal or nonverbal. It can be complementary. For instance, your slides could contain your main points, but you're also there to describe them. If someone misses it in your speech, they see it on the screen*. You can also get the important messages across again later, in the same or different words (remember the cycling that Winston referred to?).

* This does not mean that what is on the screen should be what is said. The slides complement, not replace, the oral presentation. If people are spending all their cognitive resources reading your slides, they'll fail to process what you're saying, and that is where the communication breaks down. 

Jean-luc's three laws to optimize communication are:
  • first law: adapt to your audience
  • second law: maximize the signal to noise ratio
  • third law: use effective redundancy
(but remember: second law > third law)

When studying information visualizations (graphs, charts, plots, etc.), our research team also found that when given visualizations with redundant encodings - i.e. when the message was presented in a number of ways (as a trend line, as an annotation of the trend line, as a description of the plot, in the title, etc.), human observers were more likely to recall the message correctly (different people might need to see things presented in a different way). Conversely, too many extra details, unrelated visuals, or metaphors led to worse recall and confusion, in that observers might recall only a piece of the main message, or misremember it entirely. The take-away? Make your priority getting the signal across, scrap the rest. You can do so quite effectively using the title. Importantly, if your title contains your message, more observers will remember and recall it. 

Here's a little piece of advice that also tends to repeat: make your titles count. Be it the titles of talks, slides, section headings, visualizations/graphs. Jean-luc places a lot of emphasis on this in Trees, Maps, and Theorems. He gives great examples of how scientists often caption their plots something like "Y as a function of X", where it is clear that what is plotted is, by no surprise: Y as a function of X. You haven't told the reader anything new or useful! Consider instead using this valuable real estate to convey the message of the plot, such as "Y peaks when X is at its lowest value due to the effect of...". After hearing all of Jean-luc's examples of the way scientists title their slides, figures, etc., I got to thinking. It's true, they do! 

I have since tried to be extra careful about my captions, my titles, my paper section headings, even my e-mail subject lines (I guess the current generations get a lot of twitter practice). I try to limit the noise, to imbue as much of the written text with meaning as possible, to carry across the most important points. In fact, when writing my master's thesis, I wanted the essence of the whole thesis to come through the list of contents, figures, and tables. I wanted the reader to walk away with the outlines of the story without even getting to the introduction. 

Importantly, if the message can come across simply and quickly, that is not a bad thing. If there's an easier way to say something, why not say it? Jean-luc had great anecdotes at his lecture on "Communicating science to nonscientists" about how unnecessarily jargon-filled scientific communication can be. Here are a few of my favorite anecdotes (again, paraphrased):
  • After a room full of experts took turns describing their own research topics to each other, they were asked: how many of those descriptions did you understand? Less than half. How many do you still remember? Maybe a few. And this is a room of scientists! Moreover, they consider this normal. How many talks do you remember from your last conference? How many were engaging from start to finish? (maybe... 1?)
  • When researchers are asked to describe what it is they do, and when they get to any specialized vocabulary, they tend to say it faster and to lower their voice. It is like they are trying to limit us the pain of trying to understand them by saying it fast and low. But that is exactly the opposite of what we need in order to understand! 
  • A student shows Jean-luc a passage he has written. Jean-luc looks confused and asks the student to explain what he meant to say in the passage. The student says: "Well what I mean to say is [blabla]... but I just don't know how to say it." Well in the [blabla] was exactly the explanation!
Jean-luc advises scientists "not to write complicated out of the principle of revenge" (for other scientists who write this way). Do not try to prove to the whole world how complicated your research is. Define technical words, avoid jargon, avoid synonyms, write simply. Provide reference points, comparisons, and examples. Give the why before the what.


I'll leave you on my favorite Jean-luc quote from Trees, Maps, and Theorems: "Effective communication is getting messages across. Thus it implies someone else: it is about an audience, and it suggests that we get this audience to understand something. To ensure that they understand it, we must first get them to pay attention. In turn, getting them to understand is usually nothing but a means to an end: we may want them to remember the material communicated, by convinced of it, or ultimately, act or at least be able to act on the basis of it."

And getting messages across first and foremost requires caring about the importance of getting those messages across. It is about recognizing and believing that effective communication matters. It is about adjusting your habits, your jargon, the amount of content on your slides, your projection, your figure captions and titles, and most importantly your awareness of all these things. Happy communicating!


Tuesday, 19 January 2016

Self-driving cars, internet balloons, and why Google is radical

Went to a talk about [x] today (formerly: Google[x]).

Unlike other Silicon Valley companies that are "making the world a better place" (according to Silicon Valley, the TV series), [x] is "making the world a radically better place" (according to today's presenter).

If you followed Google I/O this year or gone to some other Google talk about [x] and its moonshots, or if you've just glued yourself to the aforementioned TV series, in all three cases you would have seen the following slide:


At MIT today, we heard about 2 projects from [x] (out of the 10 or so that are currently public): self-driving cars and internet balloons.

-----

A huge problem? The 1.2 million annual traffic accidents, 93% of which are due to human error.
The radical solution: self-driving cars and the required road infrastructure.
Breakthrough tech: software with realtime sensor processing.

The principle on which this whole autonomous car thing hinges, is an initial full laser mapping of the urban area in which the car is to drive (road and buildings and all) with which the car's real-time sensor data is then aligned for accurate positioning and localization within the lane.

Is it feasible to have to pre-map every urban environment, and then to update it when it changes? Ah, well on the one hand Google Streetview cars have already shown us something about feasibility, but in the longterm, the self-driving cars will continue to collect data as they drive, driving and mapping simultaneously.

In fact, already these self-driving cars can send alerts to the other self-driving cars on the road when things look different than expected (lane closures on this street, sending you an updated map...). Such alerts also get sent to the home base for potential updates to the whole system. The cars are connected to each other and their home base via the internet. (Is this information transfer secure? Not to worry, Google knows a thing or two about internet security.)

So, some basic rules are hard-coded, but there's also a lot of machine learning from the many hours spent by these cars on the roads in all sorts of situations. These cars have to learn about the distribution of pedestrian movements (how fast they walk, how quickly they can switch direction, etc.), the typical behaviors of pedestrians, bicyclists, and pedestrians in response to bicyclists. They plot out the trajectories of all vehicles currently on the road and anticipate their next move.

The big challenge? Achieving ridiculous recall and precision. A recall of 99% when pedestrians are involved is not going to do it (you just can't afford to lose a few pedestrians here and there while you tweak your algorithm). Recall is very much about the safety of the pedestrians, but precision is also about the safety of the vehicles (and their passengers). If the car freaks out at every road sign blowing in the wind, not only will the ride be very uncomfortably jerky, but the car might swerve into other cars to avoid hitting the mistakenly classified "pedestrian".

There's other behaviors built-in for the comfort and safety of the passenger: for instance, shifting in the lane (all while avoiding other cars) when passing large trucks. Even if you have everything under control, you don't want your passenger getting antsy about a truck that's too close for comfort.

These cars also slow down at railroads, near parked cars, and while passing bicyclists. Their long-range and short-range sensors ensure the car is very much aware of its surroundings. So much so that the 15 cm resolution of its sensors allows the cars to recognize the fine hand gestures of the traffic controller waving in the middle of the intersection or the bicyclist signaling to change lanes. In making decisions, the cars also make use of all sorts of contextual information: are other cars moving? Why have they stopped? Are there traffic cones around?

And all of this computation and communication is happening on a single CPU. How's that for efficient resource sharing? (but watch out for GPUs coming to a car near you...)

These cars have been designed for zero driver assistance. Are you going to see any sort of control device built into them like a wheel or a break pedal? No chance. This is Google's approach. No need so far: of the 13 driverless car incidents to date, all were the fault of the other drivers. (Side thought: what if the sheer sight of this car on the road is distracting?)

But these cars sure go through a lot of situational testing. And yes, they're good in harsh weather conditions too (confirmed by hardware reliability tests and buckets of water). The QA testing position for the self-driving car project must be damn awesome.

-----

Another huge problem? 2/3 of the world does not have internet.
The radical solution? Balloons!
Breakthrough tech: large-scale dynamic optimization of balloon network.

We're talking global optimization (literally, global). Consider a network of balloons that are distributed around the world that need to follow pre-planned flight paths, adapt to changing wind conditions, and deal with intermittent (sometimes flaky) instructions - all while providing continuity of internet service. This is Project Loon.

Communication with these balloons as they pass over the oceans is through satellite phones. In these conditions, instructions can be dropped, intermittent, or conflicting, and the balloons must nevertheless make good decisions based on limited information and changing wind gusts.

So how does it all work? These balloons fly at an altitude of 20 km - twice as high as airplanes and the weather, so at least a few less problems to deal with. They follow air currents at different altitudes, and steer with vertical motion to end up in an air current moving in the desired direction. An internal balloon pumps air in and out, and with essentially the power of a fan, can move the exterior balloon up and down. Additional power comes from solar cells, but in most cases the wind currents are sufficient to propel the balloons.

A network of balloons thus moves through air currents, one displacing another, to provide continuous, seamless internet service to the cities below. It's kind of like how when you're moving, your service has to remain continuous despite shifting cell towers; but in this case, the city below is stationary, and it is the internet source that is moving above. This is the local optimization part.

Sometimes, balloons also need to be dispatched to the location of a natural disaster, and this has to happen fast. Balloons also need to function in all kinds of harsh conditions, and with local repair most often unavailable, redundancy is key. Redundancy, redundancy, redundancy. Remember how the self-driving cars had 1 CPU? Well these babies have upwards of 40. And if something does goes down, you have to go fetch it... wherever it ends up (can you climb trees and mountains?). Another damn awesome job.

These projects, and all the rest in the [x] repository are driven in part by the slogan: "we need to fail faster". Innovation comes from trying radically new things, and radically new things can often lead to failure. Failing faster means trying again sooner.

I gotta hand it to you, Google sells it well. Another take-away? It seems Google likes the word radical.


Sunday, 17 January 2016

Pulling together the efforts of neuroscientists and computer scientists


Had a great time last Friday at the intersection of Neuroscience and Computer Science: http://cbmm.mit.edu/science-engineering-vassar
Heard from 6 MIT Superstars: Bill Freeman, Joshua Tenenbaum, Ed Boyden, Nancy Kanwisher, Feng Zhang, and Tomaso Poggio. Learned about how neuronal cells can be stretched for physical magnification and imaging, how CRISPR can bring us neurological therapeutics, and the specialized brain areas that we may have for visual words and music. But those are just the topics I will not talk about.
Intrigued to learn more anyway?
Here are some related articles:
http://news.mit.edu/2014/crispr-technique-determines-gene-function-1210
http://news.mit.edu/2015/faculty-profile-edward-boyden-0522
http://news.mit.edu/2015/neural-population-music-brain-1216

In this post, I will focus instead on the common strands passing through the works of Bill Freeman, Joshua Tenenbaum, Josh McDermott, and Nancy Kanwisher - both to highlight the great interdisciplinary collaborations happening at MIT, and to give a broader sense of how neuroscience and computer science are informing each other, and leading to cool new insights and innovations.

Bill Freeman presented the work spearheaded by his graduate student Andrew Owens: "Visually indicated sounds". Teaming up with Josh McDermott, who studies computational audition at the MIT Department of Brain and Cognitive Sciences, they linked sound to material properties and vice versa. Given a silent video as input (of a wooden stick hitting or scratching some surface), the team developed an algorithm that synthesizes realistic sound to go along with it. To do so they needed to convert videos of different scenes (with a mixture of materials) into some perceptually-meaningful space, and link them to sounds that were also represented in some perceptually-meaningful way. What does "perceptually-meaningful" refer to? The goal is to transform the complex mess that is colored pixels and audio waveforms into some stable representations that allows similar materials to be matched together and associated with the same material properties. For instance, pictures (and videos) of different foliage will look very different from each other (the shape and the color may have almost no pixel-overlap) and yet, somehow, the algorithm needs to discover the underlying material similarity.

Here is one place where CNNs (convolutional neural nets) have been successful at transforming a set of pixels into some semantic representation (enough to perform scene recognition, object detection, and the other high-level computer vision tasks that the academic and industry communities have recently flooded the media outlets with). CNNs can learn almost human-like associations between images and semantics (like labels) or between images and other images. Owens and colleagues used CNNs to represent their silent video frames.

On the sound side of things, waveforms were converted into "cochleagrams" - stable representations of sound that allow waveforms coming from similar sources (e.g. materials, objects) to be associated with each other even if individual timestamps of the waveforms have almost no overlap. Now to go from silent video frames to synthesized sounds, RNNs (recurrent neural nets) were used (RNNs are great for representing and learning sequences, by keeping around information from previous timesteps to make predictions for successive timesteps). The cochleagrams predicted by the RNNs could then be transformed back into sound, the final output of the algorithm. More details in their paper.

This work is a great example of the creative new problems that computer vision researchers are tackling. With the powerful representational architectures that deep neural networks provide, higher and higher-level tasks can be achieved - tasks that we would typically associate with human imagination and creativity (e.g. inferring what sound is emitted by some object, what lies beyond the video frame, what is likely to happen next, etc.). In turn, these powerful architectures are interesting from a cognitive science perspective as well: how are the artificial neural networks representing different features? images? inputs? What kinds of associations, correlations, and relationships do they learn from unstructured visual data? Do they learn to meaningfully associate semantically-related concepts? Cognitive scientists can give computer scientists some ideas about which representations may be reasonable for different tasks, given what is known from decades of experiments on the human brain. But the other side of the story is that computer scientists can prod these artificial networks to learn about the representational choices that the networks have converged on, and then cognitive scientists can design experiments to check if the networks in the human brain do the same. This allows the exploration of a wide space of hypotheses at low cost (no poking human brains required), to narrow down the focus of cognitive scientists in asking whether the human brain has converged on similar representations (or if not, how can it be more optimal?)

Nancy Kanwisher mentioned how advances in deep neural networks are helping to understand functional representation in the brain. Kanwisher has done pioneering work on functional specialization in the brain (which brain areas are responsible for which of our capabilities) - including discovering the fusiform face area (FFA). In her talk, she discussed how the "Principle of Modular Design" (Marr, 1982) just makes sense - it is more efficient. She mentioned some examples of work from MIT showing there are specialized areas for faces, language, visual words, even theory of mind. By giving human participants different tasks to do and scanning their brain (using fMRI), neuroscientists can test hypotheses about the function of different brain regions (they check whether the brain signal in those regions changes significantly as they give participants different tasks to do). Some experiments, for instance, have demonstrated that certain language-specific areas of the brain are not involved during logic tasks, arithmetic, or music (tasks that are sometimes hypothesized to depend on language). Experiments have shown that the brain's specialization is not all natural selection, and that specialized brain areas can develop as a child learns. Other experiments (with Josh McDermott) have shown that uniquely-human brain regions exist, like ones selective to music and human speech (but not other sounds). Other experiments probe causality: what happens if specific brain regions are stimulated or dysfunctional? How are the respective functions affected or impaired? Interestingly, stimulating the FFA using electrodes can cause people's representations of faces to change. Correspondingly, stimulating other areas of the brain using TMS can cause moral judgements to shift.

Kanwisher is now working with Josh Tenenbaum to look for areas of the brain that might be responsible for intuitive physical inference. Initial findings are showing that the regions activated during intuitive physics reasoning are the same ones responsible for action planning and motor control. Knowing how various functional areas are laid out in the brain, how they communicate with each other, and which resources they pool together, can help provide insights for new artificial neural architectures. Conversely, artificial neural architectures can help us support or cast doubt on neuroscience hypotheses by replicating human performance on tasks using different architectures (not just the ones hypothesized).

Josh Tenenbaum is working on artificial architectures that can make the same inferences humans make, but also make the same mistakes (for instance, Facebook's AI that reasons about the stability of towers of blocks, makes different incorrect predictions than humans). The best CNNs today are great at the tasks for which they are trained, sometimes even outperforming humans, but often also making very different mistakes. Why is it not enough to just get right what humans get right, without also having to get wrong what they get wrong? The mistakes humans make are often indicative of the types of broad inferences they are capable of, and uncover the generalizing power of the human mind. This is why one-shot learning is possible: humans can learn whole new concepts from a single example (and Tenenbaum has many demos to prove it). This is why we can explain, imagine, problem solve, and plan. Tenenbaum says: "intelligence is not just pattern recognition. It is about modeling the world", and by this he means "analysis by synthesis".

Tenenbaum wants to re-engineer "the game engine in your head". His group is working on probabilistic programs that can permit causal inference. For example, their algorithm can successfully recognize the parameters of a face (shape and texture; the layout and type of facial features) as well as the lighting and viewing angle used for the picture. Their algorithm does this by sampling from a generative model that iteratively creates and refines new faces, and then matching the result to the target face. Once a match is found, the parameters chosen for the synthesized face can be considered a good approximation for the parameters of the target face. Interestingly, this model, given similar tasks as humans (e.g. to determine if two faces are the same or different) takes similar amounts of time (corresponding to task difficulty) and makes similar mistakes. This is a good hint that the human brain might be engaged in a similar simulation/synthesis process during recognition tasks.

Tenenbaum and colleagues have made great strides in showing how "analysis by synthesis" can be used to solve and achieve state-of-the-art performance on difficult tasks like face recognition, pose estimation, and character identification (even passing the visual Turing test). As is the case for much of current neural network research, the original inspiration comes from the 80s and 90s. In particular, Hinton's Helmholtz Machine had a wake-sleep cycle where recognition tasks were interspersed with a type of self-reinforcement (during "sleep") that helped the model learn on its own, even when not given new input. This approach helps the model gain representational power, and might give some clues as well about human intelligence (what do we do when we sleep?).

How does the human mind make the inferences it does? How does it jump to its conclusions? How does it transfer knowledge gained on one task and apply it to a novel one? How does it learn abstract concepts? How does it learn from a single example? How does the human mind represent the world around it, and what physical structures are in place in order to accomplish this? How is the brain wired? These questions are driving all of the research described here and will continue to pull together the efforts of neuroscientists and computer scientists in the coming years more than ever before. Our new and ever-developing tools for constructing artificial systems and probing into natural ones are establishing more and more points of contact between fields. Symposia such as these can give one a small hint of what the tip of the iceberg might look like.

Wednesday, 30 December 2015

"Computer Behind Pixar": Teaching Computational Thinking for 3D Modeling and Representation

How do you teach a group of middle- or high-schoolers about computer graphics without setting them down in a computer lab or showing them code? How do you teach them about 3D geometry without writing down a single mathematical formula on the board? And how, without doing all these things, can you nevertheless equip them with the vocabulary and intuition to be able to discuss and understand concepts in computer graphics, geometry, and representation?
Pinart toy: what better way to explain height fields?

That was our goal, and our chosen plan of attack was to flood the senses: let our students touch and explore physical models, work through group activities, watch video clips, participate in class discussions, and see demos. We filled our classroom with 3D printed models of various materials, faceted animal shapes, wooded mannequins, pin art boards, crayons and fuzzy pipe cleaners. 
What do all these objects have in common?

These physical models serve as examples and applications of different representational choices, including voxel grids, meshes, and height fields. Having physical examples to point to and explore can launch a discussion of different representational (3D modeling) choices.

Splash 2015 @ MIT

On November 22, 2015, Hijung Valentina Shin, Adriana Shulz, and I taught a 2-hour high-school class as part of MIT's yearly Splash! program - a Fall weekend during which thousands of high-schoolers flood hundreds of MIT's classrooms to be taught anything and everything. 

In our Splash! classroom, we sought to ask and answer the following questions: How is an animated character created? How can we represent different types of 3D structures? What kind of modeling decisions are made for a special effects film? What techniques do anthropological reconstruction, 3D printing, and game design have in common?

Importantly, we believed that these questions could be answered on an intuitive level, with no mathematical prerequisites. What better way to motivate the study of the mathematical and computational sciences than to give students a faint whiff of the awesome things they would be able to accomplish and think about in greater depth if armed with the right tools? 

Computational thinking to the rescue!

Here I will briefly outline the structure of our 2-hour class and the decisions made along the way, to provide possible inspiration for similar classroom activities and lessons. For the benefit of others, we have made all our slides available online.

Coding without coding

Target shape that one student described to the other using only
a set of provided primitives: colored squares, line segments, or
polygonal shapes.
Our ice-breaker activity first introduced the concepts of representational primitives and algorithmic decisions. Students split up into pairs, armed with grids and sketching utensils (colored crayons or pencils). One student was given a target shape, a set of primitives, and instructions. The goal was to supply one's partner with a sufficient and clear recipe to reproduce the target shape as accurately as possible. Some students could only specify one grid cell at a time with coordinates and a target color. Another set of instructions armed students with a ruler and the ability to specify starting and ending coordinates of line segments. A third group of students had polygonal shape rulers – e.g. triangles, squares, circles. Students could tell their partners to center a shape at specific coordinates.
Polygonal primitives
(ordered on Amazon)

Overall, we gave different student pairs different primitives:
  • pixels (colored squares)
  • line segments
  • polygonal shapes
We gave all students the same amount of time to complete this activity in pairs (15 minutes), after which students showed off their creations to their partners and other students in the class. These creations were hung around the classroom at the amusement of the students.

This gave us a great launching pad for discussion about the trade-offs between representational accuracy and algorithmic efficiency. We asked students: What did you find easy and hard? Were there parts of the shape that were well represented by your primitives? Could everything be represented by the primitives? What took you the longest? How many individual primitives did you end up using?

This kind of activity (or variants of it) is a good intro to programming activity, as students have to think about formalizing clear step-by-step instructions for their partner to carry out. The full instructions and templates for our activity are included here.


Computer behind Pixar

Inspired by the recent hype around Pixar* and particularly Boston Museum of Science's temporary Pixar exhibit, we called our class "Computer behind Pixar". The common goal of the exhibit and other educational media about Pixar is to hook in the general public with the beloved animations and characters for the purpose of introducing and motivating the underlying mathematical and scientific concepts. In fact, Mike from Monsters Inc. served as a repeating element throughout our activities, though we branched beyond Pixar, and beyond animation more generally. 


* Reference links on the topic of math behind Pixar:


We described and showed a video about the rendering pipeline*, and drew attention to the importance of modeling at the core of this pipeline, as the initial step that all future steps crucially depend on. We defined modeling as a mathematical representation composed of primitives. 
The rest of our discussion centered around different representational choices and their properties.


* More rendering resources:
Video about rendering in Pixar
Article about rendering in "Inside Out"
Character rendering (dark knight)
Rendering pipeline summary


Tangible examples of 3D representations


3D printed models are a tangible
demonstration of discretization and
the resolution issue.

Voxel grids

We introduced the concept of discretization, necessary for the representation of shapes in digital computers: 2D shapes as pixels and 3D shapes as voxels. We reminded students of the ice-breaker activity where grid cells were used as primitives.   
We then discussed voxel grids as one form of representation for 3D objects, commonly used for 3D printing. We talked about the resolution issue: the trade-off between accuracy and efficiency. We passed around physical 3D printed models at various resolutions, similar to the models pictures on the right.

Physical models to demonstrate the
differences between volumetric and
boundary representations. One is much
lighter! Why? It requires less material
to represent (and store).

Triangular meshes

In talking about efficiency, we introduced the notion of boundary representations, specifically meshes, for representing 3D objects without having to represent and explicitly store all the internal voxels (the volume). 
We connected the boundary representation to the ice-breaker activity, where in 2D, line segments were used to represent the target shape's boundary. We then showed students a demo of MeshLab, and passed around physical examples of volumetric and boundary representations.

CSG


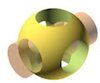
We moved on to discuss how simple shapes can be combined with different operations to create more complex shapes, in 3D via constructive solid geometry (CSG). We reminded students that the ice-breaker activity also contained polygonal primitives in 2D. For 3D, we showed students a demo of OpenScad and discussed primitive operations (union, intersection, difference, ...) that can be performed on shapes. Applications in manufacturing were discussed. 

Height Fields

Heigh fields were introduced with the help of pin art boards, as pictured at the beginning of this article. Students played with the pin boards and considered again the concepts of discretization and the representation issue. We asked students: which kind of shapes or surfaces can be represented this way and which can not?

Procedural Modeling

The grass in Pixar's Brave was created with procedural modeling,
using parametric curves and randomness.
A great hands-on demo of this kind of modeling can be found on:
 Khan Academy's Pixar-in-a-Box.
We discussed how shapes could be created by specifying procedures on primitives (aside from the primitive operations in CSG). We showed demos of solids of revolution (what better way to motivate the concept that for most students appears for the first time only in college calculus?).   We discussed how procedures like revolution and extrusion can be performed along different paths to create all sorts of complex shapes. We discussed how these paths can be further parametrized so that the revolution or extrusion procedure changes along the path. We introduced randomness as another concept that can be used to add variability to the representation.
We discussed applications to modeling trees, forests, grassy fields, crowds, and cities.

3D Representation        Primitives                Operations (recipe)                   
Voxel grids                   Voxels                     Material specification for each voxel
Triangle mesh               Triangles                 List of triangles with locations
CSG                              Basic shapes            CSG operations (union, intersection, etc.)
Height field                  Points with height    Assignment of heights to points
Procedural model         Basic shapes            Procedure (e.g. extrusion along path)


A new way to look at things

With our class, we hoped to give students a look at the modeling decisions that underly all the animated films, video games, and special effects they see on a daily basis. We wrapped up our class with a thought exercise, putting students in the position of making decisions about how to model different objects. We told them to think about the different representations we discussed: the primitives and operations required. We told them to consider the trade-off between accuracy and efficiency. Given a representation, we also told them to think about its usability - what kind of use cases are being considered, e.g. whether the modeled object needs to be animated and how. Students were asked to brainstorm how they would model the following objects: buildings, cities, fabric, hair, grass, water. Along the way, we showed them image and video demos (all these links can be found in the slides). We passed around more physical models. Together, we watched a video "behind special effects" that showcased the kinds of 3D models used in movies, a great visual review of the many representations covered in our class. We told students to look around and realize that 3D modeling decisions underlie many other applications: special effects in films, video games, simulations, anthropological reconstructions, product design, urban planning, robotics, and 3D printing. To be reminded that they have been armed with a new way to look at things, students took home polygonal stickers.